DeepSeek-V3 vs GPT-4o-mini Cost Audit (2026): High-Volume Production Unit Economics
GPT-4o-mini ($0.15/1M in, $0.60/1M out) is 44% cheaper than uncached DeepSeek-V3 ($0.27/1M in, $1.10/1M out) on raw list price. However, when disk KV-caching hits >= 80% on large system prompts, DeepSeek-V3's cached input drops to $0.07/1M—slightly beating GPT-4o-mini's $0.075/1M cached input while delivering frontier-class 671B MoE reasoning.
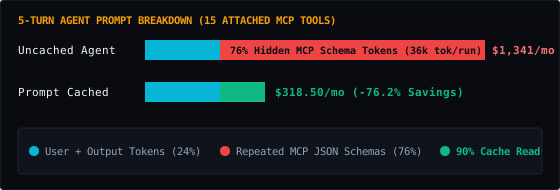
Full-Stack 4-Layer Cost & Break-Even Calculator
Layer 1: Workflow Orchestration Cost Comparison
| Platform / Tier | Billed Units / Mo | Base Plan | Overage Fee | Monthly Total | 12-Month TCO | Action |
|---|---|---|---|---|---|---|
| n8n Self-Hosted (Docker + Queue VPS) OPTIMAL | 50,000 | $14.50 | $0.00 | $14.50/mo | $174.00/yr | Deploy → |
| Make.com (Core / Pro Plan) | 200,000 | $10.59 | $224.20 | $234.79/mo | $2,817.48/yr | Deploy → |
| n8n Cloud (Starter / Pro) | 50,000 | $24.00 | $285.00 | $309.00/mo | $3,708.00/yr | Deploy → |
| Pipedream (Advanced Compute Credits) | 50,000 | $29.00 | $480.00 | $509.00/mo | $6,108.00/yr | Deploy → |
| Zapier (Professional Tier) | 150,000 | $29.99 | $5,746.13 | $5,776.12/mo | $69,313.44/yr | Deploy → |
Layer 2: Multi-Turn LLM & Hidden MCP Schema Tax Comparison
| LLM Model | Cumul. Input / Task | Hidden MCP Tokens / Task | MCP Schema Tax / Mo | Monthly LLM Total |
|---|---|---|---|---|
| Google Gemini 2.5 Flash (Google) | 18,510 tok | 6,840 tok | $20.52/mo | $99.05/mo |
| OpenAI GPT-4o-mini (OpenAI) | 19,230 tok | 7,560 tok | $34.02/mo | $126.05/mo |
| DeepSeek-V3 (671B MoE) (DeepSeek) | 19,050 tok | 7,380 tok | $40.59/mo | $183.88/mo |
| DeepSeek-R1 (Chain-of-Thought) (DeepSeek) | 19,050 tok | 7,380 tok | $81.92/mo | $370.23/mo |
| Claude 3.5 Haiku (Anthropic) | 20,310 tok | 8,640 tok | $96.77/mo | $514.37/mo |
| OpenAI o3-mini (Reasoning) (OpenAI) | 19,770 tok | 8,100 tok | $267.30/mo | $942.15/mo |
Production cost trajectory modeled at 3 base nodes, 1 iterator items/run across 0 loop nodes, and 3 agent turns with 6 MCP tools attached:
| Monthly Scale | Total Operations (1x Loop) | n8n Self-Hosted | n8n Cloud | Make.com Core | Zapier Pro | LLM API (deepseek-v3) |
|---|---|---|---|---|---|---|
| 1,000 runs/mo | 4,000 ops | $14.50 | $24.00 | $10.59 | $116.62 | $3.69 |
| 5,000 runs/mo | 20,000 ops | $14.50 | $39.00 | $22.39 | $578.62 | $18.40 |
| 10,000 runs/mo | 40,000 ops | $14.50 | $69.00 | $45.99 | $1,156.12 | $36.77 |
| 25,000 runs/mo | 100,000 ops | $14.50 | $159.00 | $116.79 | $2,888.62 | $91.95 |
| 50,000 runs/mo | 200,000 ops | $14.50 | $309.00 | $234.79 | $5,776.12 | $183.88 |
| 100,000 runs/mo | 400,000 ops | $14.50 | $609.00 | $470.79 | $11,551.12 | $367.77 |
Key Findings & Billing Mechanics
- Cached Input Parity: At 80% cache hit ratio on a 5,000-token system prompt, DeepSeek-V3 and GPT-4o-mini differ by less than $8.50 per 50,000 runs on input tokens.
- Output Token Spread: GPT-4o-mini and Gemini 2.5 Flash remain 45% cheaper on output tokens ($0.60/1M vs $1.10/1M).
DeepSeek API timeout retries inside Make.com or Zapier during peak Asia/US overlap hours can double orchestrator operation consumption if retry backoff is not handled inside code.
Production Architecture Recommendation
Use GPT-4o-mini or Gemini 2.5 Flash for high-throughput extraction, routing, and classification. Use DeepSeek-V3 when GPT-4o-mini fails complex multi-step code or SQL generation but GPT-4o ($2.50/$10) is too expensive.