AI Data, Web Scraping & Vector DB Cost Audit (2026): Firecrawl vs Jina & Supabase vs Pinecone
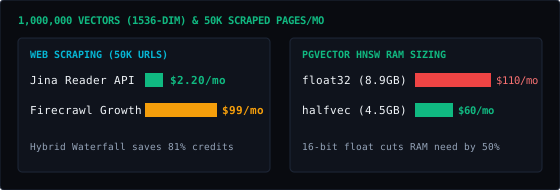
For under 500,000 vectors (1536-dim), Supabase Pro ($25/mo + $15 compute add-on) beats Pinecone Serverless Standard ($50/mo minimum floor). For AI web scraping, Jina Reader ($0.02/1M tokens) is 4.8x cheaper than Firecrawl on static documentation, while Firecrawl ($19/3k pages) wins on anti-bot SPA pages requiring headless browser actions.
Full-Stack 4-Layer Cost & Break-Even Calculator
Layer 1: Workflow Orchestration Cost Comparison
| Platform / Tier | Billed Units / Mo | Base Plan | Overage Fee | Monthly Total | 12-Month TCO | Action |
|---|---|---|---|---|---|---|
| n8n Self-Hosted (Docker + Queue VPS) OPTIMAL | 15,000 | $14.50 | $0.00 | $14.50/mo | $174.00/yr | Deploy → |
| n8n Cloud (Starter / Pro) | 15,000 | $24.00 | $75.00 | $99.00/mo | $1,188.00/yr | Deploy → |
| Pipedream (Advanced Compute Credits) | 15,000 | $29.00 | $130.00 | $159.00/mo | $1,908.00/yr | Deploy → |
| Make.com (Core / Pro Plan) | 375,000 | $10.59 | $430.70 | $441.29/mo | $5,295.48/yr | Deploy → |
| Zapier (Professional Tier) | 360,000 | $29.99 | $13,831.13 | $13,861.12/mo | $166,333.44/yr | Deploy → |
Layer 2: Multi-Turn LLM & Hidden MCP Schema Tax Comparison
| LLM Model | Cumul. Input / Task | Hidden MCP Tokens / Task | MCP Schema Tax / Mo | Monthly LLM Total |
|---|---|---|---|---|
| Google Gemini 2.5 Flash (Google) | 9,080 tok | 1,520 tok | $2.14/mo | $23.82/mo |
| OpenAI GPT-4o-mini (OpenAI) | 9,240 tok | 1,680 tok | $2.84/mo | $25.35/mo |
| DeepSeek-V3 (671B MoE) (DeepSeek) | 9,200 tok | 1,640 tok | $4.18/mo | $43.50/mo |
| DeepSeek-R1 (Chain-of-Thought) (DeepSeek) | 9,200 tok | 1,640 tok | $8.49/mo | $87.91/mo |
| Claude 3.5 Haiku (Anthropic) | 9,480 tok | 1,920 tok | $12.67/mo | $135.19/mo |
| OpenAI o3-mini (Reasoning) (OpenAI) | 9,360 tok | 1,800 tok | $22.28/mo | $187.44/mo |
Production cost trajectory modeled at 4 base nodes, 10 iterator items/run across 2 loop nodes, and 2 agent turns with 2 MCP tools attached:
| Monthly Scale | Total Operations (10x Loop) | n8n Self-Hosted | n8n Cloud | Make.com Core | Zapier Pro | LLM API (gemini-2-5-flash) |
|---|---|---|---|---|---|---|
| 1,000 runs/mo | 25,000 ops | $14.50 | $24.00 | $28.29 | $925.12 | $1.58 |
| 5,000 runs/mo | 125,000 ops | $14.50 | $39.00 | $146.29 | $4,621.12 | $7.94 |
| 10,000 runs/mo | 250,000 ops | $14.50 | $69.00 | $293.79 | $9,241.12 | $15.88 |
| 25,000 runs/mo | 625,000 ops | $14.50 | $159.00 | $736.29 | $23,101.12 | $39.70 |
| 50,000 runs/mo | 1,250,000 ops | $14.50 | $309.00 | $1,473.79 | $46,201.12 | $79.39 |
| 100,000 runs/mo | 2,500,000 ops | $14.50 | $609.00 | $2,948.79 | $92,401.12 | $158.78 |
Key Findings & Billing Mechanics
- HNSW Index RAM Formula: Storing `N` vectors of dimension `d` in pgvector HNSW requires roughly `N * d * 4 * 1.45` bytes of RAM. 1,000,000 OpenAI 1536-dim vectors require ~8.9GB RAM to avoid disk thrashing.
- Firecrawl `/extract` Credit Multiplier: Calling `/scrape` for clean Markdown costs 1 credit/URL, whereas `/extract` with structured schema extraction consumes 4–5 credits/URL.
Pinecone Serverless charges Read Units based on namespace scan size; unpartitioned multi-tenant indexes without metadata filtering or tenant namespaces can burn 10x more Read Units per query.
Production Architecture Recommendation
Combine Jina Reader (`r.jina.ai`) as primary zero-cost Markdown fetcher with Firecrawl as automatic fallback on 403/JS-heavy targets, and store embeddings in half-precision (`halfvec` 16-bit float) on Supabase pgvector to cut RAM requirements by 50%.