Voice AI Agent True Per-Minute Cost Audit (2026): Retell vs Vapi vs Bland vs Realtime API
Never budget Voice AI using headline platform fees ($0.05–$0.07/min). Once you unbundle Deepgram STT ($0.012), LLM tokens ($0.025), ElevenLabs Turbo TTS ($0.042), Twilio SIP ($0.014), and 60-second rounding rules, true production cost lands between $0.125/min (Retell modular) and $0.334/min (OpenAI Realtime API without context truncation).
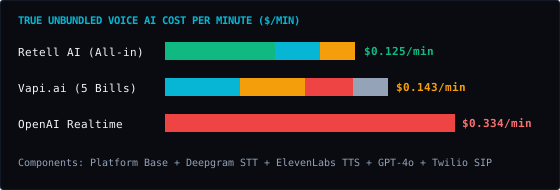
Full-Stack 4-Layer Cost & Break-Even Calculator
Layer 1: Workflow Orchestration Cost Comparison
| Platform / Tier | Billed Units / Mo | Base Plan | Overage Fee | Monthly Total | 12-Month TCO | Action |
|---|---|---|---|---|---|---|
| n8n Self-Hosted (Docker + Queue VPS) OPTIMAL | 5,000 | $14.50 | $0.00 | $14.50/mo | $174.00/yr | Deploy → |
| Make.com (Core / Pro Plan) | 20,000 | $10.59 | $11.80 | $22.39/mo | $268.68/yr | Deploy → |
| n8n Cloud (Starter / Pro) | 5,000 | $24.00 | $15.00 | $39.00/mo | $468.00/yr | Deploy → |
| Pipedream (Advanced Compute Credits) | 5,000 | $29.00 | $30.00 | $59.00/mo | $708.00/yr | Deploy → |
| Zapier (Professional Tier) | 15,000 | $29.99 | $548.63 | $578.62/mo | $6,943.44/yr | Deploy → |
Layer 2: Multi-Turn LLM & Hidden MCP Schema Tax Comparison
| LLM Model | Cumul. Input / Task | Hidden MCP Tokens / Task | MCP Schema Tax / Mo | Monthly LLM Total |
|---|---|---|---|---|
| Google Gemini 2.5 Flash (Google) | 17,790 tok | 6,840 tok | $2.82/mo | $11.70/mo |
| OpenAI GPT-4o-mini (OpenAI) | 18,510 tok | 7,560 tok | $3.97/mo | $13.53/mo |
| DeepSeek-V3 (671B MoE) (DeepSeek) | 18,330 tok | 7,380 tok | $5.54/mo | $21.67/mo |
| DeepSeek-R1 (Chain-of-Thought) (DeepSeek) | 18,330 tok | 7,380 tok | $11.22/mo | $43.81/mo |
| Claude 3.5 Haiku (Anthropic) | 19,590 tok | 8,640 tok | $15.90/mo | $64.73/mo |
| OpenAI o3-mini (Reasoning) (OpenAI) | 19,050 tok | 8,100 tok | $31.19/mo | $101.32/mo |
Production cost trajectory modeled at 3 base nodes, 1 iterator items/run across 0 loop nodes, and 6 agent turns with 3 MCP tools attached:
| Monthly Scale | Total Operations (1x Loop) | n8n Self-Hosted | n8n Cloud | Make.com Core | Zapier Pro | LLM API (openai-gpt-4o-mini) |
|---|---|---|---|---|---|---|
| 1,000 runs/mo | 4,000 ops | $14.50 | $24.00 | $10.59 | $116.62 | $2.71 |
| 5,000 runs/mo | 20,000 ops | $14.50 | $39.00 | $22.39 | $578.62 | $13.53 |
| 10,000 runs/mo | 40,000 ops | $14.50 | $69.00 | $45.99 | $1,156.12 | $27.06 |
| 25,000 runs/mo | 100,000 ops | $14.50 | $159.00 | $116.79 | $2,888.62 | $67.66 |
| 50,000 runs/mo | 200,000 ops | $14.50 | $309.00 | $234.79 | $5,776.12 | $135.32 |
| 100,000 runs/mo | 400,000 ops | $14.50 | $609.00 | $470.79 | $11,551.12 | $270.63 |
Key Findings & Billing Mechanics
- The 5-Invoice Surprise on Vapi: Vapi's $0.05/min fee covers orchestration only; adding ElevenLabs + GPT-4o + Deepgram + Twilio brings actual per-minute burn to $0.143/min.
- 60-Second Rounding & Outbound Dial Tax: On Bland AI, a 70-second call rounds to 2.0 billed minutes (+71% inflation), and high-volume outbound dialers pay $0.015 per unanswered/voicemail attempt.
- Realtime API Audio Context Snowball: OpenAI's Speech-to-Speech API re-ingests prior audio turns on every response; a 10-minute support call costs 2.2x more per minute in minute 9 than in minute 1 unless sliding-window truncation is configured.
Reserved concurrency lines ($8–$12/line/month) often cost more than per-minute usage for bursty B2B campaigns that dial 100 simultaneous leads during a 1-hour morning window.
Production Architecture Recommendation
Use Retell AI with Cartesia/ElevenLabs Flash and GPT-4o-mini for predictable per-second B2B phone agents ($0.11–$0.125/min all-in). Use ElevenLabs Conversational AI when ultra-low latency emotional voice synthesis is the top conversion driver.