Vapi.ai vs Bland AI Cost Audit (2026): 60-Second Rounding & Unanswered Outbound Tax
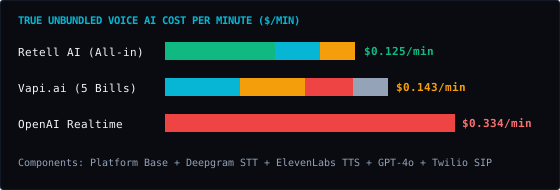
On paper, Bland AI ($0.09/min) looks 37% cheaper than a full Vapi stack ($0.143/min). In reality, for an outbound B2B campaign dialing 20,000 leads where 60% go unanswered and connected calls average 75 seconds, Bland AI's $0.015 unanswered dial fee + 60-second rounding inflates effective cost by +48.2%, making per-second Vapi or Retell cheaper for short qualification calls.
Full-Stack 4-Layer Cost & Break-Even Calculator
Layer 1: Workflow Orchestration Cost Comparison
| Platform / Tier | Billed Units / Mo | Base Plan | Overage Fee | Monthly Total | 12-Month TCO | Action |
|---|---|---|---|---|---|---|
| n8n Self-Hosted (Docker + Queue VPS) OPTIMAL | 8,000 | $14.50 | $0.00 | $14.50/mo | $174.00/yr | Deploy → |
| Make.com (Core / Pro Plan) | 32,000 | $10.59 | $25.96 | $36.55/mo | $438.60/yr | Deploy → |
| n8n Cloud (Starter / Pro) | 8,000 | $24.00 | $33.00 | $57.00/mo | $684.00/yr | Deploy → |
| Pipedream (Advanced Compute Credits) | 8,000 | $29.00 | $60.00 | $89.00/mo | $1,068.00/yr | Deploy → |
| Zapier (Professional Tier) | 24,000 | $29.99 | $895.13 | $925.12/mo | $11,101.44/yr | Deploy → |
Layer 2: Multi-Turn LLM & Hidden MCP Schema Tax Comparison
| LLM Model | Cumul. Input / Task | Hidden MCP Tokens / Task | MCP Schema Tax / Mo | Monthly LLM Total |
|---|---|---|---|---|
| Google Gemini 2.5 Flash (Google) | 7,964 tok | 3,040 tok | $2.28/mo | $8.86/mo |
| OpenAI GPT-4o-mini (OpenAI) | 8,284 tok | 3,360 tok | $3.02/mo | $10.08/mo |
| DeepSeek-V3 (671B MoE) (DeepSeek) | 8,204 tok | 3,280 tok | $4.46/mo | $16.40/mo |
| DeepSeek-R1 (Chain-of-Thought) (DeepSeek) | 8,204 tok | 3,280 tok | $9.05/mo | $33.18/mo |
| Claude 3.5 Haiku (Anthropic) | 8,764 tok | 3,840 tok | $13.52/mo | $49.89/mo |
| OpenAI o3-mini (Reasoning) (OpenAI) | 8,524 tok | 3,600 tok | $23.76/mo | $75.54/mo |
Production cost trajectory modeled at 3 base nodes, 1 iterator items/run across 0 loop nodes, and 4 agent turns with 2 MCP tools attached:
| Monthly Scale | Total Operations (1x Loop) | n8n Self-Hosted | n8n Cloud | Make.com Core | Zapier Pro | LLM API (openai-gpt-4o-mini) |
|---|---|---|---|---|---|---|
| 1,000 runs/mo | 4,000 ops | $14.50 | $24.00 | $10.59 | $116.62 | $1.26 |
| 5,000 runs/mo | 20,000 ops | $14.50 | $39.00 | $22.39 | $578.62 | $6.30 |
| 10,000 runs/mo | 40,000 ops | $14.50 | $69.00 | $45.99 | $1,156.12 | $12.61 |
| 25,000 runs/mo | 100,000 ops | $14.50 | $159.00 | $116.79 | $2,888.62 | $31.51 |
| 50,000 runs/mo | 200,000 ops | $14.50 | $309.00 | $234.79 | $5,776.12 | $63.03 |
| 100,000 runs/mo | 400,000 ops | $14.50 | $609.00 | $470.79 | $11,551.12 | $126.06 |
Key Findings & Billing Mechanics
- The 75-Second Call Trap: A 75-second connected call equals 1.25 actual minutes on Vapi/Retell, but rounds to 2.00 billed minutes (+60% inflation) under 60-second rounding granularity.
- Unanswered Dial Overhead: At a 25% answer rate (3 unanswered dials per connected call), paying $0.015 per unanswered dial adds $0.045 to every connected conversation.
Failing to enable answering-machine detection (AMD) cutoff within the first 4 seconds causes your Voice AI agent to converse with customer voicemail greetings for 30+ seconds at full per-minute rates.
Production Architecture Recommendation
For cold outbound campaigns with <35% pickup rates and <90s average call duration, use Retell AI or Vapi with Twilio BYOC per-second billing and strict 3.5-second AMD hangup rules.