Retell AI vs Vapi.ai Pricing Audit (2026): True Unbundled Per-Minute Voice Cost
While Vapi advertises a $0.05/min platform fee vs Retell's $0.07/min base, Retell bundles Deepgram STT into its base rate whereas Vapi passes STT ($0.012/min), TTS ($0.042/min), LLM ($0.025/min), and Telephony ($0.014/min) through separate provider bills. At 10,000 minutes/month with ElevenLabs voices, Retell AI totals $1,250/mo ($0.125/min) vs Vapi's $1,430/mo ($0.143/min)—making Retell 12.6% cheaper with 1 consolidated invoice.
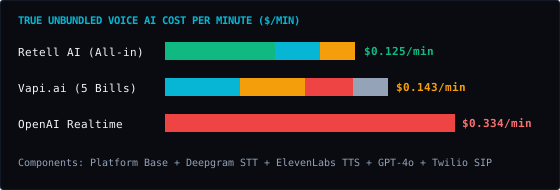
Full-Stack 4-Layer Cost & Break-Even Calculator
Layer 1: Workflow Orchestration Cost Comparison
| Platform / Tier | Billed Units / Mo | Base Plan | Overage Fee | Monthly Total | 12-Month TCO | Action |
|---|---|---|---|---|---|---|
| n8n Self-Hosted (Docker + Queue VPS) OPTIMAL | 5,000 | $14.50 | $0.00 | $14.50/mo | $174.00/yr | Deploy → |
| Make.com (Core / Pro Plan) | 20,000 | $10.59 | $11.80 | $22.39/mo | $268.68/yr | Deploy → |
| n8n Cloud (Starter / Pro) | 5,000 | $24.00 | $15.00 | $39.00/mo | $468.00/yr | Deploy → |
| Pipedream (Advanced Compute Credits) | 5,000 | $29.00 | $30.00 | $59.00/mo | $708.00/yr | Deploy → |
| Zapier (Professional Tier) | 15,000 | $29.99 | $548.63 | $578.62/mo | $6,943.44/yr | Deploy → |
Layer 2: Multi-Turn LLM & Hidden MCP Schema Tax Comparison
| LLM Model | Cumul. Input / Task | Hidden MCP Tokens / Task | MCP Schema Tax / Mo | Monthly LLM Total |
|---|---|---|---|---|
| Google Gemini 2.5 Flash (Google) | 11,230 tok | 3,800 tok | $1.78/mo | $7.89/mo |
| OpenAI GPT-4o-mini (OpenAI) | 11,630 tok | 4,200 tok | $2.36/mo | $8.89/mo |
| DeepSeek-V3 (671B MoE) (DeepSeek) | 11,530 tok | 4,100 tok | $3.49/mo | $14.57/mo |
| DeepSeek-R1 (Chain-of-Thought) (DeepSeek) | 11,530 tok | 4,100 tok | $7.07/mo | $29.46/mo |
| Claude 3.5 Haiku (Anthropic) | 12,230 tok | 4,800 tok | $10.56/mo | $44.18/mo |
| OpenAI o3-mini (Reasoning) (OpenAI) | 11,930 tok | 4,500 tok | $18.56/mo | $66.45/mo |
Production cost trajectory modeled at 3 base nodes, 1 iterator items/run across 0 loop nodes, and 5 agent turns with 2 MCP tools attached:
| Monthly Scale | Total Operations (1x Loop) | n8n Self-Hosted | n8n Cloud | Make.com Core | Zapier Pro | LLM API (openai-gpt-4o-mini) |
|---|---|---|---|---|---|---|
| 1,000 runs/mo | 4,000 ops | $14.50 | $24.00 | $10.59 | $116.62 | $1.78 |
| 5,000 runs/mo | 20,000 ops | $14.50 | $39.00 | $22.39 | $578.62 | $8.89 |
| 10,000 runs/mo | 40,000 ops | $14.50 | $69.00 | $45.99 | $1,156.12 | $17.78 |
| 25,000 runs/mo | 100,000 ops | $14.50 | $159.00 | $116.79 | $2,888.62 | $44.46 |
| 50,000 runs/mo | 200,000 ops | $14.50 | $309.00 | $234.79 | $5,776.12 | $88.91 |
| 100,000 runs/mo | 400,000 ops | $14.50 | $609.00 | $470.79 | $11,551.12 | $177.83 |
Key Findings & Billing Mechanics
- Per-Second Billing Precision: Both Retell AI and Vapi bill per second, avoiding the 35%–70% rounding inflation seen on per-minute platforms.
- Concurrency Line Economics: Retell includes 20 concurrent calls free ($8/mo per extra line), whereas Vapi includes 10 concurrent calls free ($10/mo per extra line).
Using BYOK (Bring Your Own Key) ElevenLabs on Vapi without an ElevenLabs Scale plan causes TTS overage to bill at $0.18–$0.24/1k characters (~$0.14/min for TTS alone!).
Production Architecture Recommendation
Choose Retell AI for lower all-in per-minute cost, 20 included concurrency lines, and single-invoice simplicity. Choose Vapi only if you have negotiated enterprise volume discounts directly with Deepgram and Cartesia.