Supabase pgvector vs Pinecone Serverless (2026): 1M Vectors RAM & Read Unit TCO
For startups with <500,000 vectors and relational metadata joins, Supabase Pro ($25/mo + $15 Small Compute = $40/mo) beats Pinecone Serverless Standard ($50/mo minimum commitment) and eliminates dual-database sync complexity. Above 2,000,000 1536-dim vectors with low query QPS (<5 queries/sec), Pinecone Serverless ($16–$55/mo storage + read units) becomes cheaper than provisioning a 16GB RAM dedicated Postgres instance ($110+/mo) on Supabase.
Full-Stack 4-Layer Cost & Break-Even Calculator
Layer 1: Workflow Orchestration Cost Comparison
| Platform / Tier | Billed Units / Mo | Base Plan | Overage Fee | Monthly Total | 12-Month TCO | Action |
|---|---|---|---|---|---|---|
| n8n Self-Hosted (Docker + Queue VPS) OPTIMAL | 20,000 | $14.50 | $0.00 | $14.50/mo | $174.00/yr | Deploy → |
| Make.com (Core / Pro Plan) | 100,000 | $10.59 | $106.20 | $116.79/mo | $1,401.48/yr | Deploy → |
| n8n Cloud (Starter / Pro) | 20,000 | $24.00 | $105.00 | $129.00/mo | $1,548.00/yr | Deploy → |
| Pipedream (Advanced Compute Credits) | 20,000 | $29.00 | $180.00 | $209.00/mo | $2,508.00/yr | Deploy → |
| Zapier (Professional Tier) | 80,000 | $29.99 | $3,051.13 | $3,081.12/mo | $36,973.44/yr | Deploy → |
Layer 2: Multi-Turn LLM & Hidden MCP Schema Tax Comparison
| LLM Model | Cumul. Input / Task | Hidden MCP Tokens / Task | MCP Schema Tax / Mo | Monthly LLM Total |
|---|---|---|---|---|
| Google Gemini 2.5 Flash (Google) | 6,740 tok | 1,520 tok | $2.51/mo | $20.50/mo |
| OpenAI GPT-4o-mini (OpenAI) | 6,900 tok | 1,680 tok | $3.53/mo | $23.15/mo |
| DeepSeek-V3 (671B MoE) (DeepSeek) | 6,860 tok | 1,640 tok | $4.92/mo | $37.67/mo |
| DeepSeek-R1 (Chain-of-Thought) (DeepSeek) | 6,860 tok | 1,640 tok | $9.97/mo | $75.96/mo |
| Claude 3.5 Haiku (Anthropic) | 7,140 tok | 1,920 tok | $14.13/mo | $114.55/mo |
| OpenAI o3-mini (Reasoning) (OpenAI) | 7,020 tok | 1,800 tok | $27.72/mo | $171.60/mo |
Production cost trajectory modeled at 4 base nodes, 1 iterator items/run across 0 loop nodes, and 2 agent turns with 2 MCP tools attached:
| Monthly Scale | Total Operations (1x Loop) | n8n Self-Hosted | n8n Cloud | Make.com Core | Zapier Pro | LLM API (openai-gpt-4o-mini) |
|---|---|---|---|---|---|---|
| 1,000 runs/mo | 5,000 ops | $14.50 | $24.00 | $10.59 | $155.12 | $1.16 |
| 5,000 runs/mo | 25,000 ops | $14.50 | $39.00 | $28.29 | $771.12 | $5.79 |
| 10,000 runs/mo | 50,000 ops | $14.50 | $69.00 | $57.79 | $1,541.12 | $11.58 |
| 25,000 runs/mo | 125,000 ops | $14.50 | $159.00 | $146.29 | $3,851.12 | $28.94 |
| 50,000 runs/mo | 250,000 ops | $14.50 | $309.00 | $293.79 | $7,701.12 | $57.87 |
| 100,000 runs/mo | 500,000 ops | $14.50 | $609.00 | $588.79 | $15,401.12 | $115.74 |
Key Findings & Billing Mechanics
- The $50 Pinecone Floor: Pinecone's Standard Serverless tier enforces a $50/month minimum spend even if your storage + read units only total $3.20.
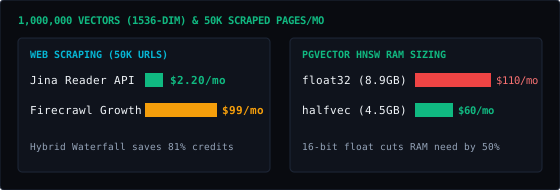
- halfvec (float16) Game Changer: Converting Supabase `vector(1536)` columns to `halfvec(1536)` cuts HNSW index memory in half, letting 1M vectors fit comfortably on a $60/mo compute tier instead of $110/mo.
Running frequent `UPDATE` statements on rows containing pgvector embeddings causes PostgreSQL MVCC dead-tuple bloat in the HNSW index unless embedding columns are isolated in a separate 1:1 sidecar table.
Production Architecture Recommendation
Use Supabase pgvector with `halfvec(1536)` for 90% of B2B RAG products under 1.5M vectors. Only move to Pinecone Serverless or Qdrant Cloud when storing >3M vectors with sparse query traffic.