Gemini 2.5 Pro vs Claude 3.7 Sonnet (2026): Long-Context & The 200k-Token Cliff Audit
At 190,000 input tokens, Gemini 2.5 Pro ($1.25/1M) costs $0.237 per call vs Claude 3.7 Sonnet's $0.570 (Gemini is 58% cheaper). But adding just 15,000 tokens to cross 205,000 tokens triggers Google's 2x cliff multiplier on the ENTIRE prompt ($2.50/1M), jumping the single call cost from $0.237 to $0.512 (+116% for 7.8% more text)!
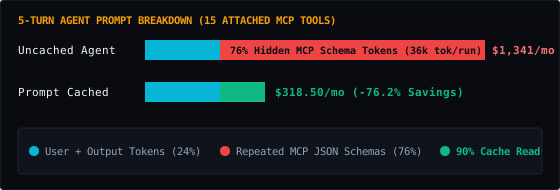
Full-Stack 4-Layer Cost & Break-Even Calculator
Layer 1: Workflow Orchestration Cost Comparison
| Platform / Tier | Billed Units / Mo | Base Plan | Overage Fee | Monthly Total | 12-Month TCO | Action |
|---|---|---|---|---|---|---|
| Make.com (Core / Pro Plan) OPTIMAL | 8,000 | $10.59 | $0.00 | $10.59/mo | $127.08/yr | Deploy → |
| n8n Self-Hosted (Docker + Queue VPS) | 2,000 | $14.50 | $0.00 | $14.50/mo | $174.00/yr | Deploy → |
| n8n Cloud (Starter / Pro) | 2,000 | $24.00 | $0.00 | $24.00/mo | $288.00/yr | Deploy → |
| Pipedream (Advanced Compute Credits) | 2,000 | $29.00 | $0.00 | $29.00/mo | $348.00/yr | Deploy → |
| Zapier (Professional Tier) | 6,000 | $29.99 | $202.13 | $232.12/mo | $2,785.44/yr | Deploy → |
Layer 2: Multi-Turn LLM & Hidden MCP Schema Tax Comparison
| LLM Model | Cumul. Input / Task | Hidden MCP Tokens / Task | MCP Schema Tax / Mo | Monthly LLM Total |
|---|---|---|---|---|
| OpenAI GPT-4o-mini (OpenAI) | 210,000 tok | 0 tok | $0.00/mo | $64.44/mo |
| Google Gemini 2.5 Flash (Google) | 210,000 tok | 0 tok | $0.00/mo | $64.44/mo |
| DeepSeek-V3 (671B MoE) (DeepSeek) | 210,000 tok | 0 tok | $0.00/mo | $116.04/mo |
| DeepSeek-R1 (Chain-of-Thought) (DeepSeek) | 210,000 tok | 0 tok | $0.00/mo | $236.26/mo |
| Claude 3.5 Haiku (Anthropic) | 210,000 tok | 0 tok | $0.00/mo | $345.60/mo |
| OpenAI o3-mini (Reasoning) (OpenAI) | 210,000 tok | 0 tok | $0.00/mo | $472.56/mo |
Production cost trajectory modeled at 3 base nodes, 1 iterator items/run across 0 loop nodes, and 1 agent turns with 0 MCP tools attached:
| Monthly Scale | Total Operations (1x Loop) | n8n Self-Hosted | n8n Cloud | Make.com Core | Zapier Pro | LLM API (gemini-2-5-pro) |
|---|---|---|---|---|---|---|
| 1,000 runs/mo | 4,000 ops | $14.50 | $24.00 | $10.59 | $116.62 | $543.00 |
| 5,000 runs/mo | 20,000 ops | $14.50 | $39.00 | $22.39 | $578.62 | $2,715.00 |
| 10,000 runs/mo | 40,000 ops | $14.50 | $69.00 | $45.99 | $1,156.12 | $5,430.00 |
| 25,000 runs/mo | 100,000 ops | $14.50 | $159.00 | $116.79 | $2,888.62 | $13,575.00 |
| 50,000 runs/mo | 200,000 ops | $14.50 | $309.00 | $234.79 | $5,776.12 | $27,150.00 |
| 100,000 runs/mo | 400,000 ops | $14.50 | $609.00 | $470.79 | $11,551.12 | $54,300.00 |
Key Findings & Billing Mechanics
- Whole-Prompt Retroactive Tiering: Crossing 200,000 input tokens on Gemini 2.5 Pro does not just bill the tokens above 200k at $2.50/1M—it re-prices the first 200,000 tokens to $2.50/1M as well.
- Chunking ROI: Splitting a 240k-token repository audit into two 120k-token calls on Gemini 2.5 Pro costs $0.30 total vs $0.60 as a single 240k call (instant 50% savings).
Google Context Caching charges a separate hourly storage fee ($1.00–$4.50 per 1M tokens/hour) in addition to per-request read fees! Leaving a 1M-token cache alive 24/7 for 30 days without TTL cleanup costs $720–$3,240/month even with 0 queries.
Production Architecture Recommendation
Enforce a hard 195,000-token prompt chunking guardrail in your code before calling Gemini 2.5 Pro, and always set explicit `ttl: '3600s'` on Google Context Caches.